Random Forest run #101 · ml_result
regression
task type
random_forest
model type
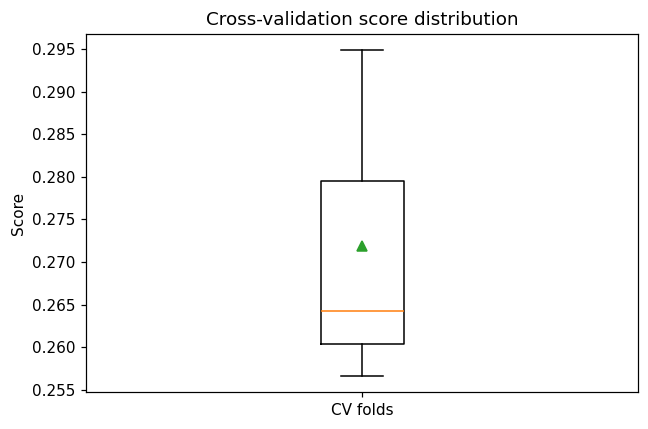
0.2719
r2 mean
0.01656
r2 std
completed
status
2026-09-21 02:12
created
Figures
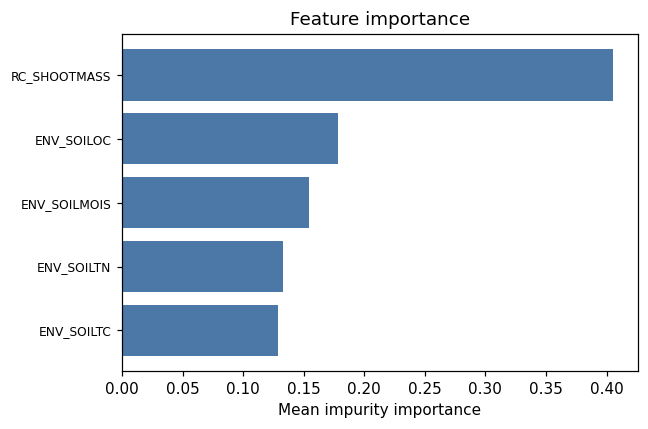
Feature importance
Download PNG
Cross-validation score distribution
Download PNG
Pipeline Stages 3 rows
| stage | detail |
|---|---|
| preprocessing | missing values: mean |
| feature_selection | kbest_f (k=5); 40 → 5 features |
| model | random_forest (regression), 3-fold cross-validation |
Feature Importance 5 rows
| name | value |
|---|---|
| ENV_SOILOC | 0.17793142045738233 |
| ENV_SOILTN | 0.13315263001126423 |
| ENV_SOILTC | 0.12896309611900642 |
| ENV_SOILMOIS | 0.1542793735085912 |
| RC_SHOOTMASS | 0.4056734799037558 |
Split Metrics 3 rows
| r2 | mse |
|---|---|
| 0.29488470576300163 | 65.11308921118005 |
| 0.2641873562717668 | 69.04177119580399 |
| 0.25658696732146336 | 55.71141053536753 |
Method & Provenance
- Method
- Random Forest
- Method key
ml_result(result type:ml_result, result #101)- Engine
- Python · scikit-learn v1.8.0
- Dataset(s)
- #690 gallery — cat_g_field_data_plots.csv
- Status
- completed
- Permanent link
- https://cat-g-omxpert.wishartlab.com/results/by-token/a316fb7a42834890a899475de981b6f9 Bookmark or share this URL — it does not depend on your session.
- Created
- 2026-09-21 02:12:52.641122
Parameters used
| Parameter | Value |
|---|---|
model_type
| random_forest |
target_column
| PC_SHOOTMASS |
n_splits
| 3 |
Execution trace
Reconstructed from the parameters stored with this result — represents the Python/R calls the analysis service made.
# Models compared via app.services.ml_model_registryscores = sklearn.model_selection.cross_val_score(model, X, y, cv=3)