Result Detail – Repeated Measures
Result Information
- Result ID
- 191
- Type
- Repeated Measures
- Status
- completed
- Dataset ID
- 709
- Created
- 2026-09-21 02:16:57.609141
Statistical Test Result
- Test
- repeated measures — repeated_measures
- Statistic
- 2.7067
- p-value
- 0.1111
- Interpretation
- not significant Repeated-measures ANOVA over 3 timepoints (n=30 subjects) with between-subject factor group
Repeated-measures ANOVA table
| Term | df | df (error) | F | p |
|---|---|---|---|---|
| group (between) | 1.0 | 28.0 | 2.707 | 0.1111 |
| time | 2.0 | 56.0 | 30.667 | 1.013e-09 |
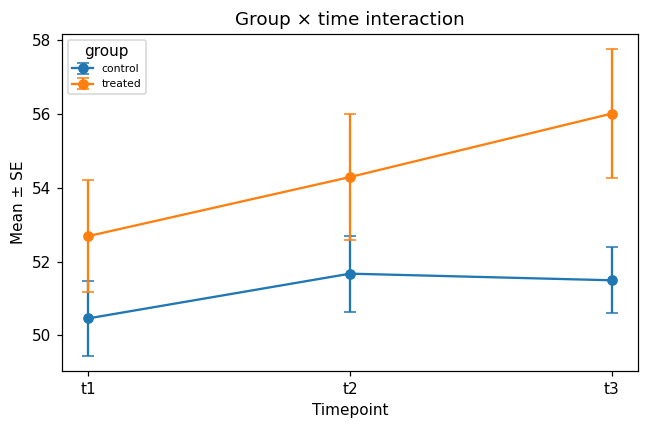
| time × group | 2.0 | 56.0 | 9.444 | 0.0002922 |
Means by group × timepoint
| group | t1 | t2 | t3 |
|---|---|---|---|
| control | 50.4634 | 51.6751 | 51.4951 |
| treated | 52.6927 | 54.2930 | 56.0131 |
Per-timepoint means
| Timepoint | Mean |
|---|---|
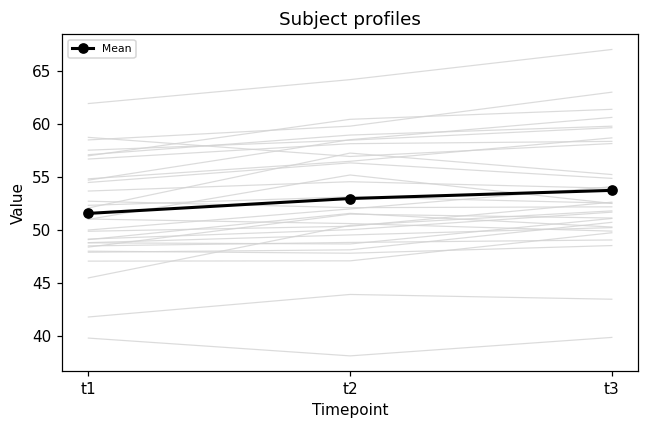
| t1 | 51.5780 |
| t2 | 52.9841 |
| t3 | 53.7541 |
Figures
Subject profiles
Download PNG
Group × time interaction
Download PNG
Derived Dataset — Ready for Downstream Analysis
The output of this run was saved as a new dataset, gallery — example_repeated_measures.csv (long_format), which you can select in any downstream analysis (machine learning, statistical tests, further preprocessing, or feature selection).
Preview Dataset Open in Editor Run Another Analysis →Pathway Analysis (same dataset)
Method & Provenance
- Method
- Repeated-measures ANOVA
- Method key
repeated_measures(result type:statistical_test, result #191)- Engine
- Python · statsmodels v0.14.6
- Dataset(s)
- #709 gallery — example_repeated_measures.csv
- Status
- completed
- Permanent link
- https://cat-g-omxpert.wishartlab.com/results/by-token/912162730f9b4e7f9d1dca324562f4e7 Bookmark or share this URL — it does not depend on your session.
- Created
- 2026-09-21 02:16:57.609141
Parameters used
| Parameter | Value |
|---|---|
test_type | repeated_measures |
timepoint_cols | t1, t2, t3 |
between_col | group |
Execution trace
Reconstructed from the parameters stored with this result — represents the Python/R calls the analysis service made.
from statsmodels.stats.anova import AnovaRMfit = AnovaRM(long_df, depvar='value', subject='subject', within=['time']).fit()