Result Detail – Random Forest
Result Information
- Result ID
- 150
- Type
- Random Forest
- Status
- completed
- Dataset ID
- 704
- Created
- 2026-09-21 02:16:24.643806
- Saved Model
- Available — Download .pkl
Model Parameters
- Model Type
- classification
- Estimators
- 60
- Max Depth
- None
Pre-Modeling Statistics (Pearson, Spearman, ANOVA)
| Feature | Pearson r | Pearson p | Pearson FDR | Spearman ρ | Spearman FDR | ANOVA F | ANOVA FDR | Significant? |
|---|---|---|---|---|---|---|---|---|
| f1 | -0.4773 | 0.0000 | 0.0000 | -0.4682 | 0.0000 | 34.8210 | 0.0000 | ✓ Yes |
| f2 | 0.3454 | 0.0001 | 0.0002 | 0.3592 | 0.0001 | 15.9873 | 0.0002 | ✓ Yes |
| f3 | 0.1152 | 0.2104 | 0.2104 | 0.1205 | 0.1898 | 1.5859 | 0.2104 | ✗ No |
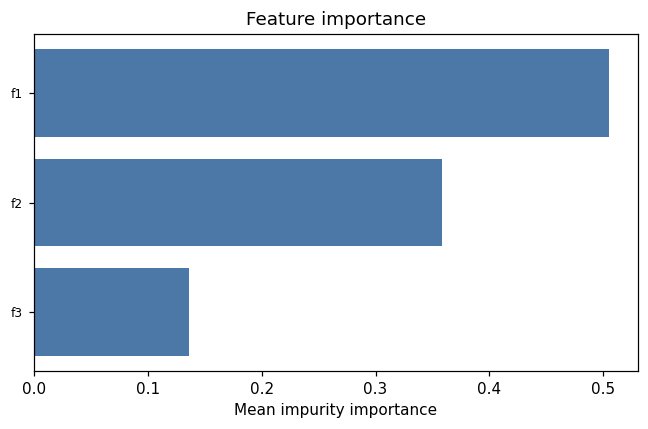
Feature Importance (Random Forest)
| Rank | Feature | Importance (Mean) | SD |
|---|---|---|---|
| 1 | f1 | 0.5051 | 0.0176 |
| 2 | f2 | 0.3585 | 0.0214 |
| 3 | f3 | 0.1364 | 0.0057 |
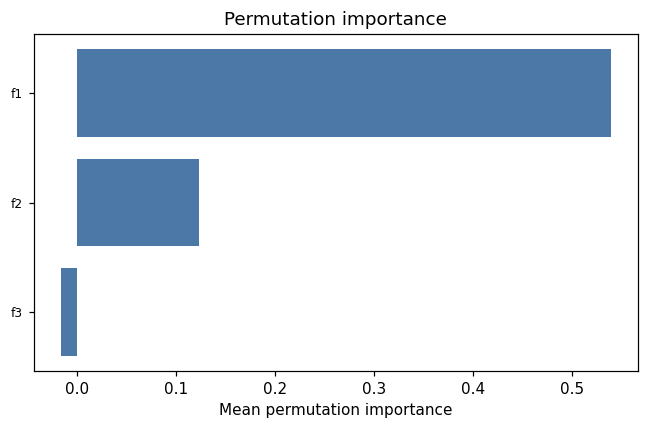
Permutation Importance
| Rank | Feature | Perm. Importance (Mean) | SD |
|---|---|---|---|
| 1 | f1 | 0.5389 | 0.0535 |
| 2 | f2 | 0.1233 | 0.0546 |
| 3 | f3 | -0.0156 | 0.0137 |
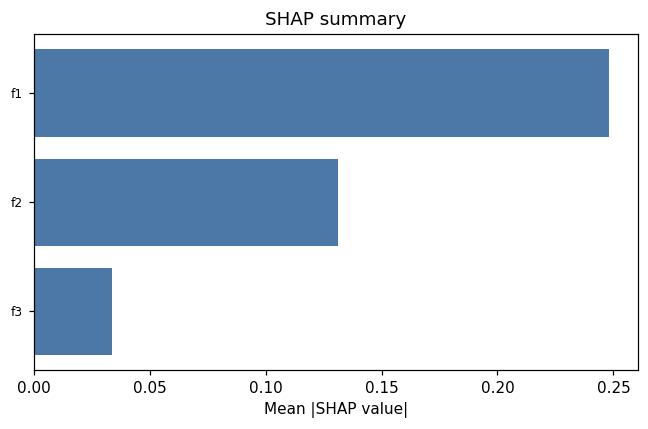
SHAP Feature Importance
| Rank | Feature | SHAP Mean |Abs| |
|---|---|---|
| 1 | f1 | 0.2482 |
| 2 | f2 | 0.1312 |
| 3 | f3 | 0.0339 |
Model Metrics
Classification
| Split | Accuracy | F1 (weighted) |
|---|---|---|
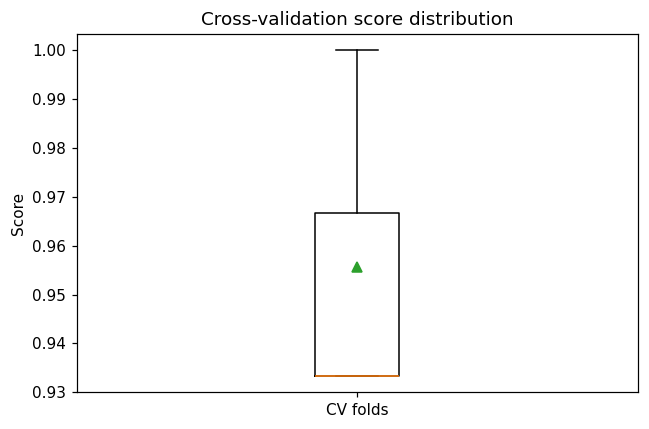
| Split 1 | 0.9333 | 0.9319 |
| Split 2 | 0.9333 | 0.9333 |
| Split 3 | 1.0000 | 1.0000 |
| Mean | 0.9556 | 0.9551 |
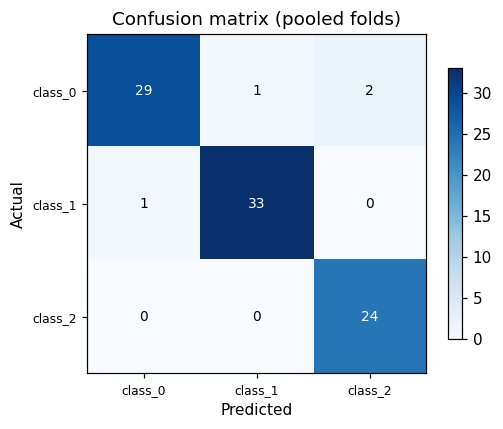
Confusion Matrix
| class_0 | class_1 | class_2 | |
|---|---|---|---|
| class_0 | 29 | 1 | 2 |
| class_1 | 1 | 33 | 0 |
| class_2 | 0 | 0 | 24 |
Figures
Feature importance
Download PNG
Permutation importance
Download PNG
SHAP summary
Download PNG
Confusion matrix
Download PNG
Cross-validation score distribution
Download PNG
Pathway Analysis (same dataset)
Method & Provenance
- Method
- Random Forest (Classification)
- Method key
random_forest(result type:random_forest, result #150)- Engine
- Python · scikit-learn v1.8.0
- Dataset(s)
- #704 gallery — example_classification.csv
- Status
- completed
- Permanent link
- https://cat-g-omxpert.wishartlab.com/results/by-token/75fc6b424d704db4b2f7621b482e84b5 Bookmark or share this URL — it does not depend on your session.
- Created
- 2026-09-21 02:16:24.643806
Parameters used
| Parameter | Value |
|---|---|
task_type | classification |
model_type | classification |
target_column | target |
n_estimators | 60 |
n_splits | 3 |
test_size | 0.25 |
run_univariate | True |
run_permutation | True |
run_shap | True |
permutation_repeats | 10 |
fdr_threshold | 0.05 |
Execution trace
Reconstructed from the parameters stored with this result — represents the Python/R calls the analysis service made.
from sklearn.ensemble import RandomForestClassifiermodel = RandomForestClassifier(n_estimators=60, random_state=42)scores = sklearn.model_selection.cross_val_score(model, X, y, cv=3)