Result Detail – Preprocessing
Result Information
- Result ID
- 34
- Type
- Preprocessing
- Status
- completed
- Dataset ID
- 690
- Created
- 2026-09-21 02:11:20.564609
Preprocessing Summary
- Steps Applied
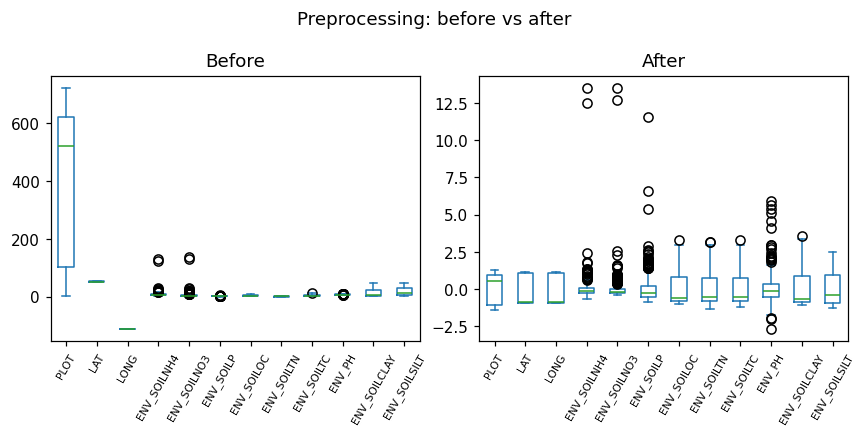
- missing value imputation normalization
- Rows (in → out)
- 400 → 400
- Features
- 40
- Target Column
- PC_SHOOTMASS
Step Parameters
| Step | Parameters |
|---|---|
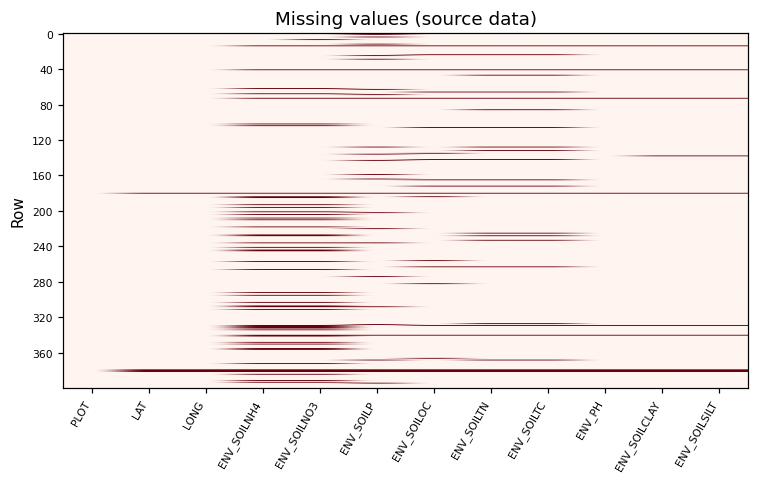
| missing value imputation | strategy = median |
| normalization | method = z-score |
Figures
Before vs after
Download PNG
Missing values
Download PNG
Derived Dataset — Ready for Downstream Analysis
The output of this run was saved as a new dataset, gallery — cat_g_field_data_plots.csv (preprocessed), which you can select in any downstream analysis (machine learning, statistical tests, further preprocessing, or feature selection).
Preview Dataset Open in Editor Run Another Analysis →Pathway Analysis (same dataset)
Method & Provenance
- Method
- Preprocessing
- Method key
preprocessing(result type:preprocessing, result #34)- Engine
- Python · pandas/scikit-learn v3.0.3
- Dataset(s)
- #690 gallery — cat_g_field_data_plots.csv
- Status
- completed
- Permanent link
- https://cat-g-omxpert.wishartlab.com/results/by-token/eb7eb2770d9b4a1cbd47e9bc2da501e5 Bookmark or share this URL — it does not depend on your session.
- Created
- 2026-09-21 02:11:20.564609
Parameters used
| Parameter | Value |
|---|---|
normalization | {'method': 'z-score'} |
steps | missing_value_imputation → normalization |
Execution trace
Reconstructed from the parameters stored with this result — represents the Python/R calls the analysis service made.
# app.services.preprocessing_service.PreprocessingService# step: missing_value_imputation# step: normalizationdf_out = service.apply(df, steps=steps, params=params)